We did the heavy lifting in 2025. Here’s what it

Voice AI Training Data and Speech Data Collection at Scale

Annotated speech, conversation, and emotion data for teams building voice agents, IVR systems, and conversational AI, on the same platform and QC stack behind Taskmonk's other production AI data.
ai services

Beyond Transcription: Data for Voice AI Agents That Read the Room

Your team already knows Taskmonk handles transcription and speaker diarization. Here's what it takes to train a voice agent that understands tone, context, and conversation flow.
Emotion & Sentiment Annotation
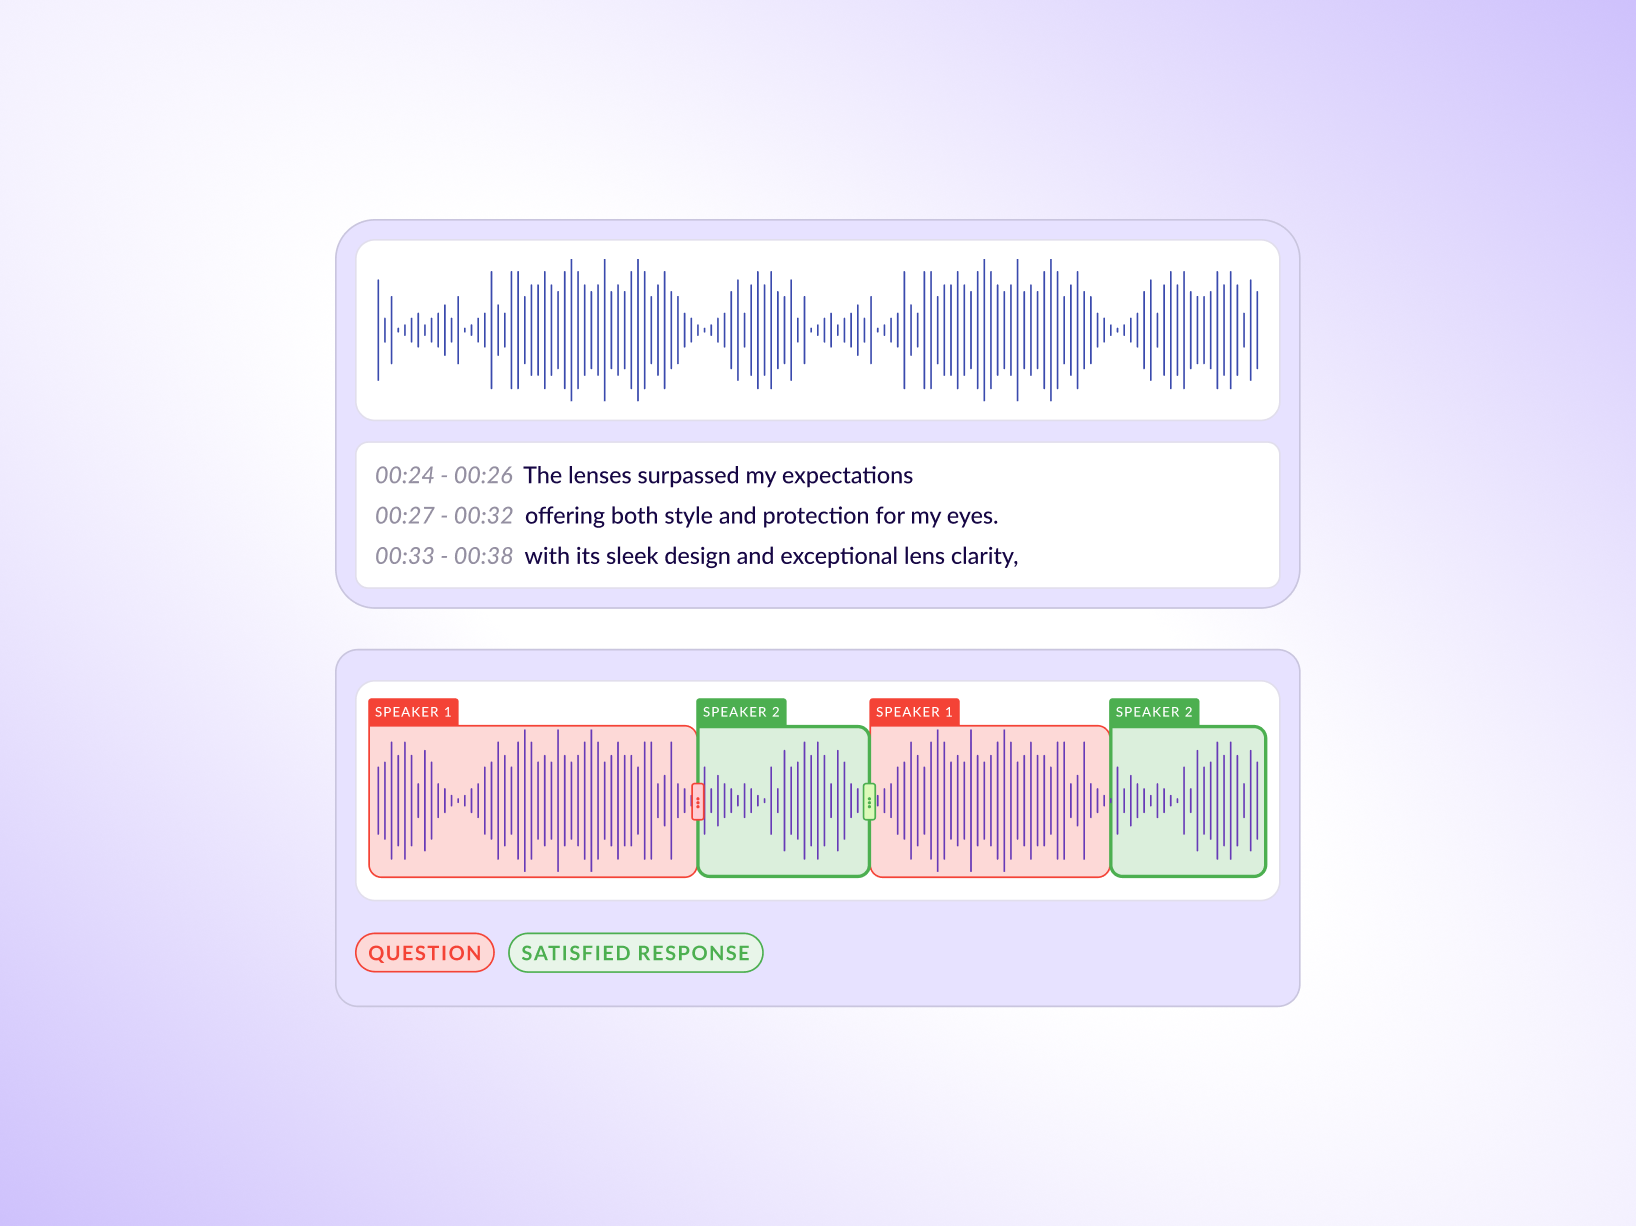
Emotional state, sentiment, stress level, tone, and confidence scoring, tagged at the utterance or turn level.
Conversation Annotation
Turn segmentation, dialogue flow, intent transitions, interruptions, escalation points, and resolution outcomes.
Audio Event Annotation
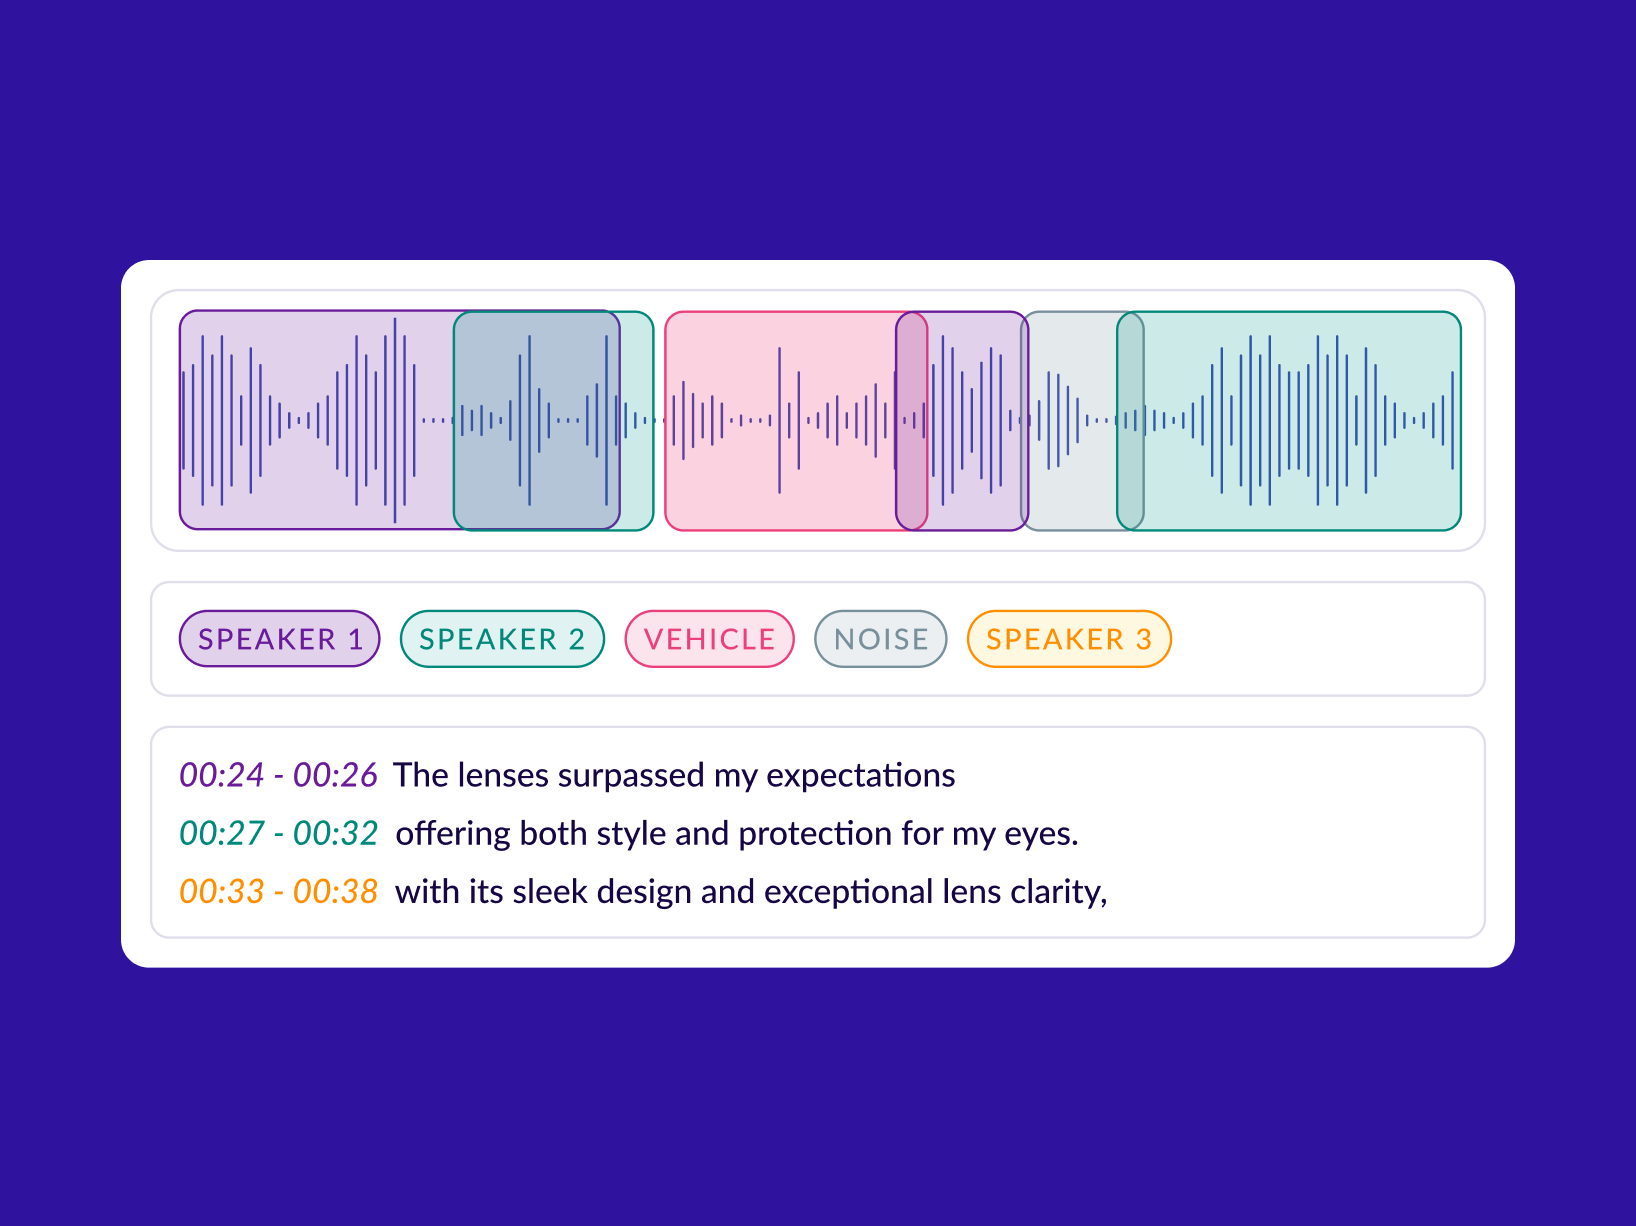
Background noise, music, silence, overlapping speech, laughter, and alarms, plus Taskmonk's filler-tag taxonomy
Need transcription and speaker diarization? You can find more details abt this on our Audio Annotation page.
arrow up

Get the Raw Audio Before You Even Get to Annotation

End-to-end speech data collection, from recruiting contributors to a validated, consented, quality-checked dataset, powered by Nimble, Taskmonk's own mobile companion app.
custom code
Contributor onboarding and script distribution.
custom code
Mobile and web recording via Nimble, Taskmonk's native Android and iOS app for audio, video, and image collection in the field.
custom code
Consent Module: work is blocked until consent is accepted, gating every recording session by default.
custom code
Demographic capture (where appropriate) and consent management.
custom code
Automated audio quality checks before data enters the pipeline.

Voice AI Datasets That Reflect How People Actually Talk

Accent, dialect, speech rate, recording environment, and device type, captured so your model doesn't just work in a quiet studio.
custom code
Speech rate and clarity, age group tagging.
custom code
Noise level, recording environment, microphone/device type.
custom code
Accent and language identification, dialect tagging, and speaker metadata including gender and nativity.
custom code
Multilingual and code-switched speech support, with per-project multi-language configuration.

Voice AI, Wherever a Conversation Needs to Be Understood

The same conversation-and-emotion annotation stack adapts to the vertical.
Voice AI for Healthcare Operations · Voice-Enabled Physical AI & Robotics · AI Recruiters and Interviewers · Voice AI for Manufacturing · In-Car AI Assistants · Voice-First Operating Systems for Businesses
research
CASE STUDY
arrow-up
Indic Language Audio Annotation, 90 to 95% transcription accuracy across nine languages, up from a 50 to 60% baseline, for a Voice AI training-data provider

FAQ

How is this different from Taskmonk's Audio Annotation page?
Audio Annotation covers the core audio annotation tool and tooling, transcription, diarization, and segmentation. Voice AI builds on top of that for teams training conversational agents, adding emotion, sentiment, and conversation-level annotation.
Can Taskmonk annotate emotion and sentiment in speech data?
Yes, emotional state, sentiment, stress level, tone, and confidence are tagged at the utterance or turn level.
Does Taskmonk handle multi-turn conversation data, not just single audio clips?
Yes, conversation annotation covers turn segmentation, dialogue flow, intent transitions, interruptions, and resolution outcomes.
What if my audio isn't clean studio recordings?
Taskmonk's audio labeling and audio data annotation workflows account for background noise, overlapping speech, and varied recording environments and device types as standard.
Can Taskmonk help collect voice data, not just annotate what I already have?
Yes, via Nimble, Taskmonk's own mobile companion app, covering contributor onboarding, recording, environment validation, consent, and quality checks before data reaches the annotation pipeline.
Does this support multiple languages and accents?
Yes, including code-switched and multilingual speech annotation across 25+ languages, accent and dialect tagging, and, like the Indic Language case study above, native-speaker annotation across nine languages.

Give Your Voice AI Something Real to Learn From

Emotion, conversation, and context-aware speech data, not just transcripts.