IntelligentDocumentProcessing
for Model-Ready Data
Document automation that extracts, classifies, and validates data from invoices, forms, contracts, and scanned documents, powered by Mistral OCR and GPT-4o, verified by humans
AI Document Processing, Built on Named Models You Can Verify
Powered by Mistral OCR, Mistral Document Query, and GPT-4o.
Mistral OCR
Raw text extraction from scanned, handwritten, and low-quality documents.
Mistral Document Query
Natural-language field extraction, ask for a field, get it back structured, no manual template-building.
GPT-4o generative model processor
Prompt-to-structured-JSON extraction, combinable with OCR for documents that need both raw text and interpreted fields.
Named Entity Recognition (NER)
Entities, key-value pairs, and relationships tagged for downstream model training.
Classification & routing
Document type, language, and quality tagging before extraction begins.
Translation & transliteration
Multi-language document support.
50M+ Invoices Processed Across 75 Countries
99.9% accuracy on field extraction across diverse invoices, human-verified, not model output taken at face value.
50M+
Invoices Processed
75
Countries
99.9%
Accuracy, Human-verified
Supported document types
Document automation for PDFs, forms, bank statements, and contracts using OCR/ICR, NER, and table extraction.
Medical Records
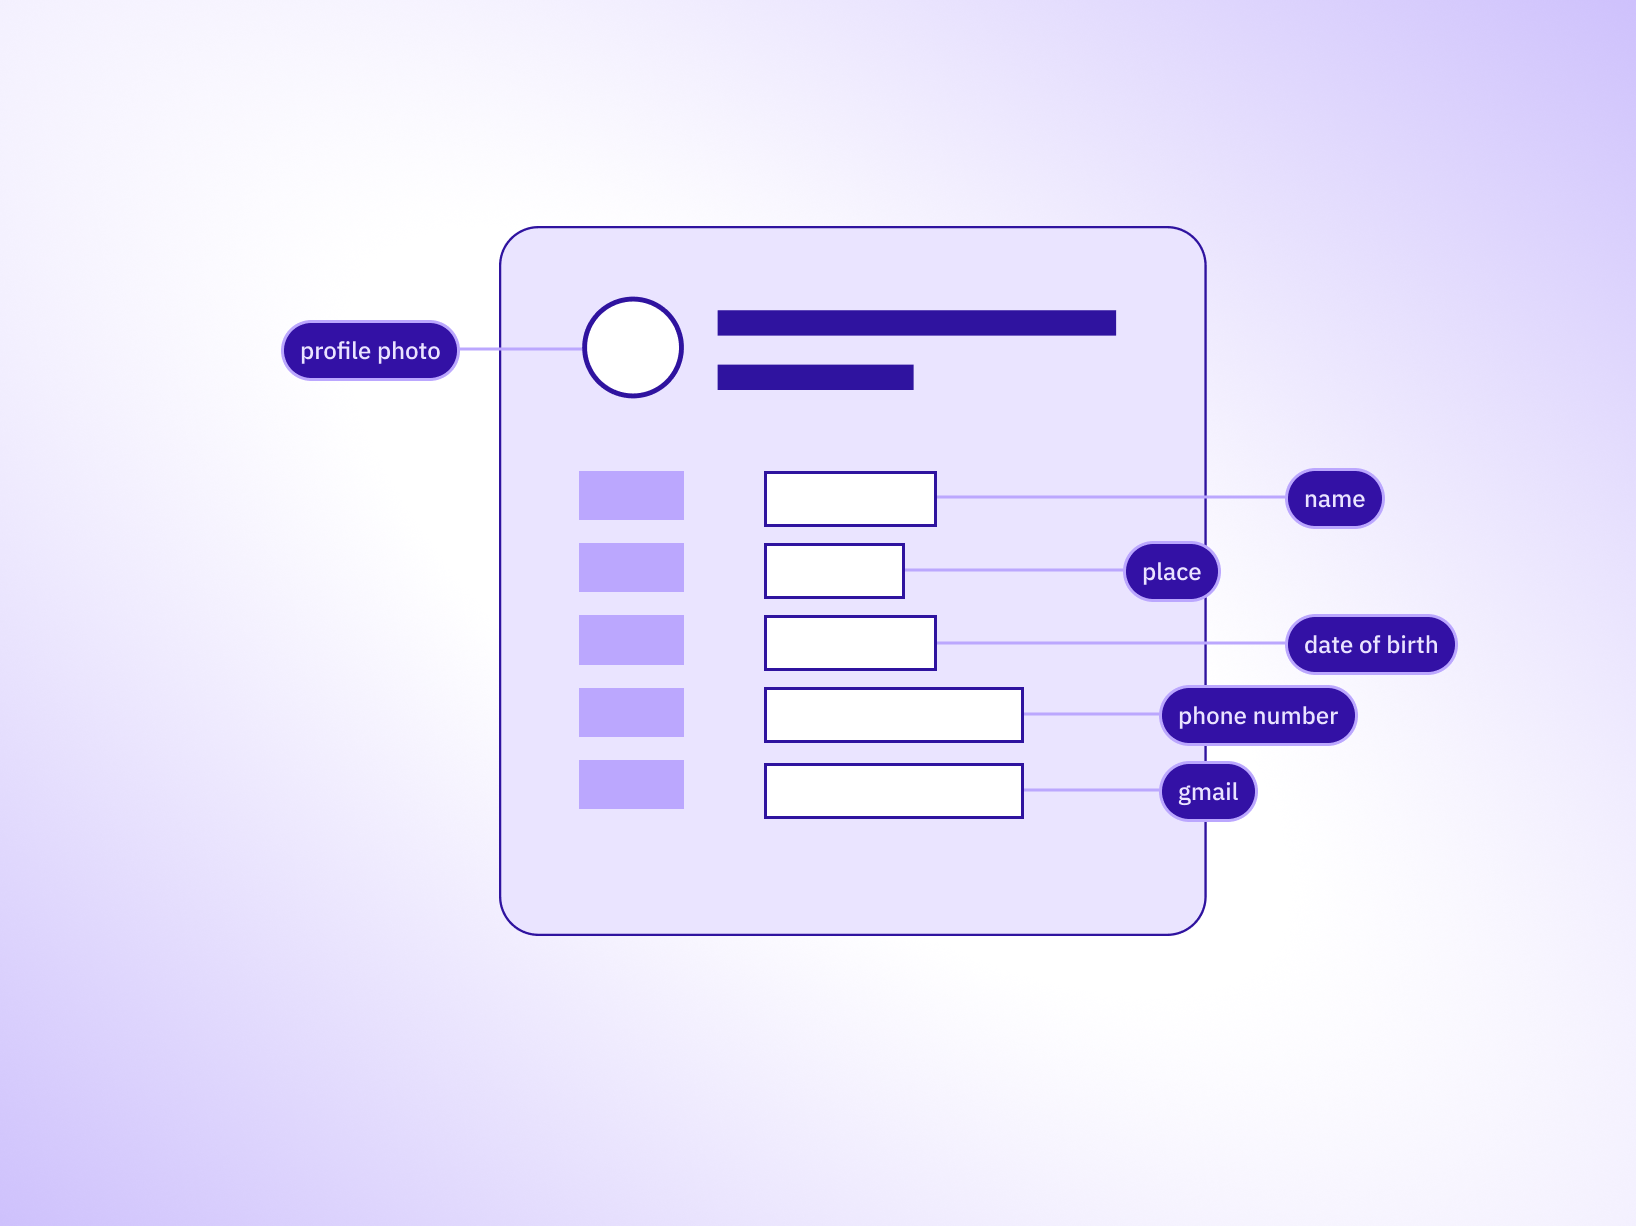
Extract patient identifiers, diagnoses, and provider details from records and claims; flag missing fields for review
PDFs
Extract text with layout coordinates, reference spans, and correct skew or glare for reliable verification.
Invoices, Receipts, and Statements
Capture headers, line items, currencies, and taxes; reconcile totals and normalize formats for ERP or risk analysis.
Contracts, Forms, Affidavits
Pull clauses, parties, dates, signatures, and required fields; keep each value anchored to the source text.
Handwriting, Signatures, Stamps
Read cursive, verify signatures visually, detect stamps and seals, and route uncertain regions for review.
Emails and Attachments
Ingest email bodies and files, preserve sender and time metadata, and process mixed attachments uniformly.
Multi-Page Packets
Detect document and page types, split bundles precisely, and maintain cross-page references for audit trails.
Images
OCR photos and scans, de-noise, deskew, and anchor extracted text to pixels for citation.
Multilingual and multi-script docs
Process major scripts and locales, normalize dates and numbers, and consistently export structured outputs.
IDs Proofs
Extract names, numbers, experiences, and addresses from passports, licenses, and utility bills with confidence checks.
Who Taskmonk's Document AI Is Built For
Built for AI/ML teams training document-understanding models across BFSI, e-commerce, healthcare, and media
Healthcare
Digitize medical records, claims forms, and EHR intake packets. Extract patient identifiers, diagnoses, provider details, and codes. Flag missing or inconsistent fields for review. Export structured, audit-ready records that keep PHI handling compliant.
Finance
Automate KYC/KYB packs, bank statements, and chargeback bundles. Extract IDs, names, amounts, and balances. Reconcile totals. Flag mismatches for review. Export clean JSON to core banking or risk systems without spreadsheet cleanup.
Insurance
Process ACORD forms, FNOL packets, and loss runs reliably. Detect document or page type. Pull parties, dates, coverage limits, and line-items. Reconcile sums. Route low-confidence fields to adjusters. Keep decisions span-grounded for audits.
Tax
Normalize W-2/1099/1040 and GST/VAT invoices into consistent schemas. Handle multi-page tables, currency and date formats, and line-item totals. Export to ERP/AP. Reduce month-end rework with validation rules that catch silent errors.
Legal
Turn contracts, NDAs, and discovery bundles into structured fields. Extract clauses, parties, obligations, renewal dates, and governing law. Anchor each value to a source span. Version changes so reviews and redlines stay traceable.
Lending
Speed up applications, disclosures, and income proofs. Validate identity, incomes, and liabilities. Map line-items across pay stubs and statements. Link supporting documents. Export decisions with citations to ensure underwriting remains explainable and compliant.
Public Sector & Compliance
Digitize permits, filings, and regulatory reports. Enforce required fields and ranges. Keep multilingual formats straight. Preserve audit trails. Export standardized records so compliance teams can review decisions, not spend time fixing document formatting.
Enterprise level security for AI document processing in high stake use cases
Span-level audit trails, field-level PII masking, SSO/RBAC, and end-to-end encryption—deployed in your VPC. Your documents stay private and secure
Provenance & Data Handling
Span-level audit trails track every field: who extracted or edited it, when, and why. Labels have version history, exports are consistent and repeatable, and there are data retention/deletion policies. Data leaving the system is tightly controlled.
Access, Masking & Encryption
SSO/SAML enforce login security, with least-privilege role-based access, IP address allowlists, and rules for session length. Data is encrypted using TLS while moving and AES-256 when stored. Personal data is protected during document scanning and validation, with restricted previews available to outside contractors.
Residency, Deployment & Sector Controls
Pin processing to your region, restrict exports, and run in a single-tenant VPC or on-prem with private networking. Add compliance requirements your data needs: SOC 2 Type II base, PCI considerations for card data, and HIPAA/BAA for PHI.
Move from Manual Data Entry to Verified Extraction with Taskmonk
Named models, automatic exception routing, and human verification on every field that matters.
When our Auto annotation models can't resolve a field with certainty, the platform flags it and routes it for review automatically — reviewers work the exceptions, not every field on every document.
Qualified Human Expertise: Maker-checker on the fields that matter
A second reviewer verifies flagged extractions before data ships, which is why the 99.9% invoice-accuracy figure is human-verified rather than a raw model-confidence score
Beyond Documents
The modality pages your document pipeline will actually touch
What level of accuracy can we expect for document text extraction?
On invoices specifically, Taskmonk has processed 50M+ across 75 countries at 99.9% field-level accuracy. This is achieved with OCR and generative extraction working together: text extraction plus structured-field parsing, with a second reviewer checking every flagged field before data ships. Baseline accuracy still depends on document mix. Structured invoices clear this bar fastest. Handwriting, stamps, and multi-page tables take more review passes to get there.
What’s the difference between document automation, OCR/ICR, and intelligent document processing (IDP)?
OCR (Optical Character Recognition) or ICR (Intelligent Character Recognition) converts pixels to text. IDP (Intelligent Document Processing) adds text classification, named entity recognition (NER), table extraction, and validation. Document automation wraps these with rules, HITL (human-in-the-loop) review, and exports (JSON/CSV) so work moves through core systems reliably.
Do we still need human-in-the-loop (HITL) review?
Yes—for fields with low confidence, unfamiliar document templates, handwritten text, or poor-quality scans. Human-in-the-loop (HITL) review helps identify silent failures, connects corrections to the original data source, and provides feedback for training purposes. This ensures document automation accuracy improves without interrupting production workflows.
What level of accuracy can we expect for document text extraction?
Baseline accuracy depends on the mix of document types. Focusing on key data fields, using schema checks, and employing inter-annotator agreement (IAA)-backed quality assurance (QA) can typically increase field-level accuracy into the 90th percentile. Structured invoices improve faster; however, accuracy is harder to boost for more complex sets that include handwriting, stamps, or tables spanning multiple pages.
Can LLMs replace traditional OCR/ICR + IDP stacks?
Large Language Models (LLMs) enhance document automation by helping with pre-labeling, quality assurance (QA), and answering questions from documents. However, they still rely on accurate Optical Character Recognition (OCR) or Intelligent Character Recognition (ICR) and layout detection for structured data. A recommended approach is to use OCR or ICR and IDP for extracting data, and LLMs for reasoning and validation. Use confidence thresholds and human-in-the-loop (HITL) review to ensure quality.
Are there benchmarks for “document AI” beyond marketing claims?
Yes—new community leaderboards evaluate OCR, KIE, VQA, table extraction across multiple datasets. These help compare models and set grounded expectations before pilots. We use similar task-level metrics internally.
How do costs compare between managed IDP and LLM APIs?
Practitioners note that managed doc-AI tools can be pricier but more predictable/obedient; LLMs may be cheaper per page, yet they require extra validation to avoid mistakes. A pilot with your documents clarifies the true cost-to-accuracy.
What does integration look like—and how quickly can we pilot it?
Deterministic exports (JSON/CSV/Parquet), webhooks, and APIs connect to RPA, claims, ERP, and core banking. We offer a 48-hour POC using your samples to validate document automation accuracy, throughput, and reviewer load before broader rollout.